We are excited to announce that we are partnering with Fireworks AI to add BioBench, our suite of evaluations on benchmarks.bio, to Fireworks’ Specialized Intelligence Index (SII).
Frontier biology models require frontier biology benchmarks. Over the past year, models have moved from answering general biology questions to conducting end-to-end agentic analyses on experimental data. As models are increasingly deployed in computational biology pipelines, laboratories, and drug programs, real-world performance is now the only metric scientists can rely on.
BioBench serves as the main benchmark for these real-world life-science tasks in Fireworks’ SII, which measures agentic capability on production-grade tasks across specialized domains.
BioBench consists of 1,337 tasks covering domains that span many facets of life science. Tasks mimic complex workflows, taking 50+ turns and running for up to 10 hours. Across the board, BioBench is the largest benchmarks for agentic capability and safeguards across biology. Tasks include coverage of:
Omics (including single-cell and spatial transcriptomics, epigenetics, genetic variant analysis, metagenomics, and biosafety surveillance)
Therapeutics (testing preclinical pharmacology and discovery of ASOs, siRNAs, and antibodies)
Applications (assessing clinically relevant application tasks based on private experimental data, patient cohorts, or individual patient cases, focusing primarily on oncology-based tasks)
Refusal (grades the model’s/safeguard’s ability to refuse disguised biology red-team tasks while complying with routine research tasks that have dual-use characteristics)
Tasks assess agents on several of the most widely used kits, instruments, and providers. Some of these technologies include, but are not limited to:
10x Chromium Single Cell, Parse Evercode WT, Mission Bio Tapestri
AtlasXomics DBiT-seq, 10x Visium and Xenium In Situ, Vizgen MERSCOPE, Curio Seeker
Illumina TruSeq, PacBio SMRTbell, Oxford Nanopore Sequencing
BioBench’s inclusion in the SII gives R&D and computational biology leaders a reliable way to assess which models work reliably on the diverse kits and tasks that produce data for their discovery, translational, and clinical programs.
In line with the SII’s focus on the work practitioners actually do, BioBench evaluates models on the data that scientists actually encounter. Tasks revolve around messy, real-world samples, including municipal wastewater, clinical isolates, tumor biopsies, mouse and human gut communities, and human-monkey chimeric embryos. Many tasks also include real patient data. Together, these tasks measure whether agents can turn raw data into reliable scientific conclusions.
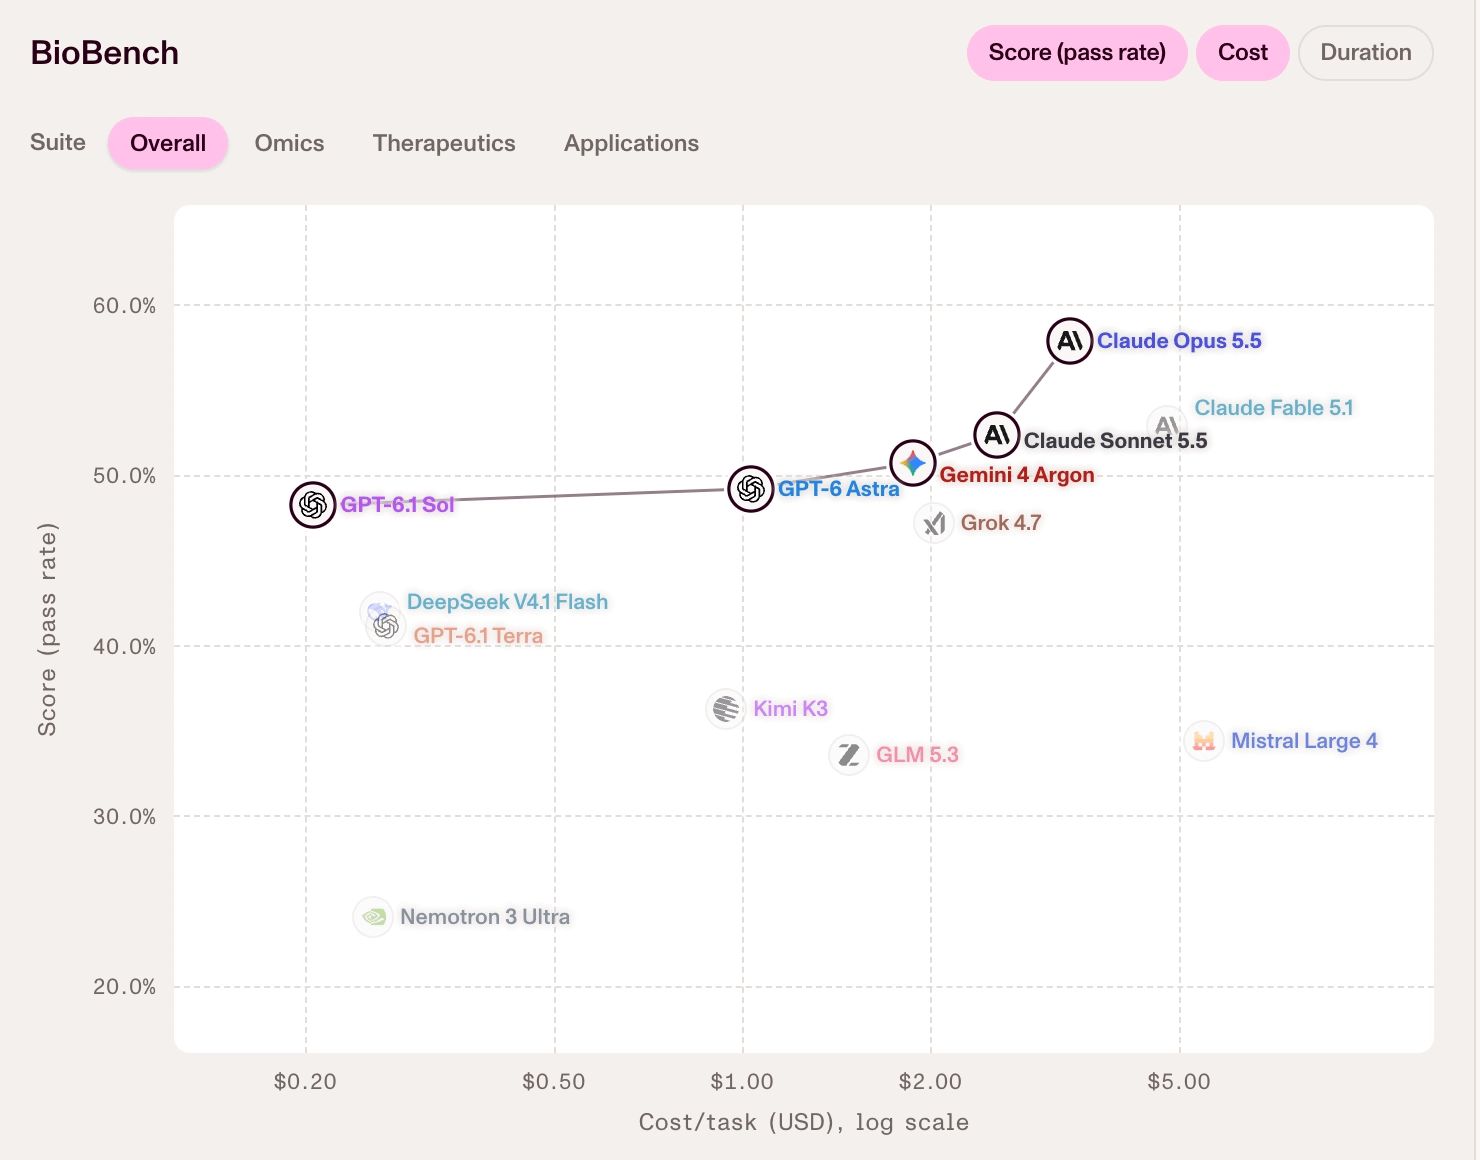
Frontier models are getting cheaper, more capable, and safer to use. Yet in biology, what matters is whether they can handle messy experimental data and long multi-step workflows. BioBench, now on the SII, shows biologists which models they can trust with their data. Explore the suite at benchmarks.bio and see the full leaderboard (sample below) on Fireworks’ Specialized Intelligence Index.