


We introduce an Antibody Discovery Benchmark, an experimentally grounded benchmark for testing whether AI agents can make scientific decisions across the stages of therapeutic antibody discovery.
The benchmark contains 100 evaluations spanning ten areas of antibody discovery, from target and modality selection through assay design, binder discovery, binding characterization, cellular pharmacology, engineering, and preclinical candidate de-risking. Each evaluation asks agents to inspect experimental evidence, choose an appropriate analysis, and use the result to make a decision relevant to a preclinical antibody program.
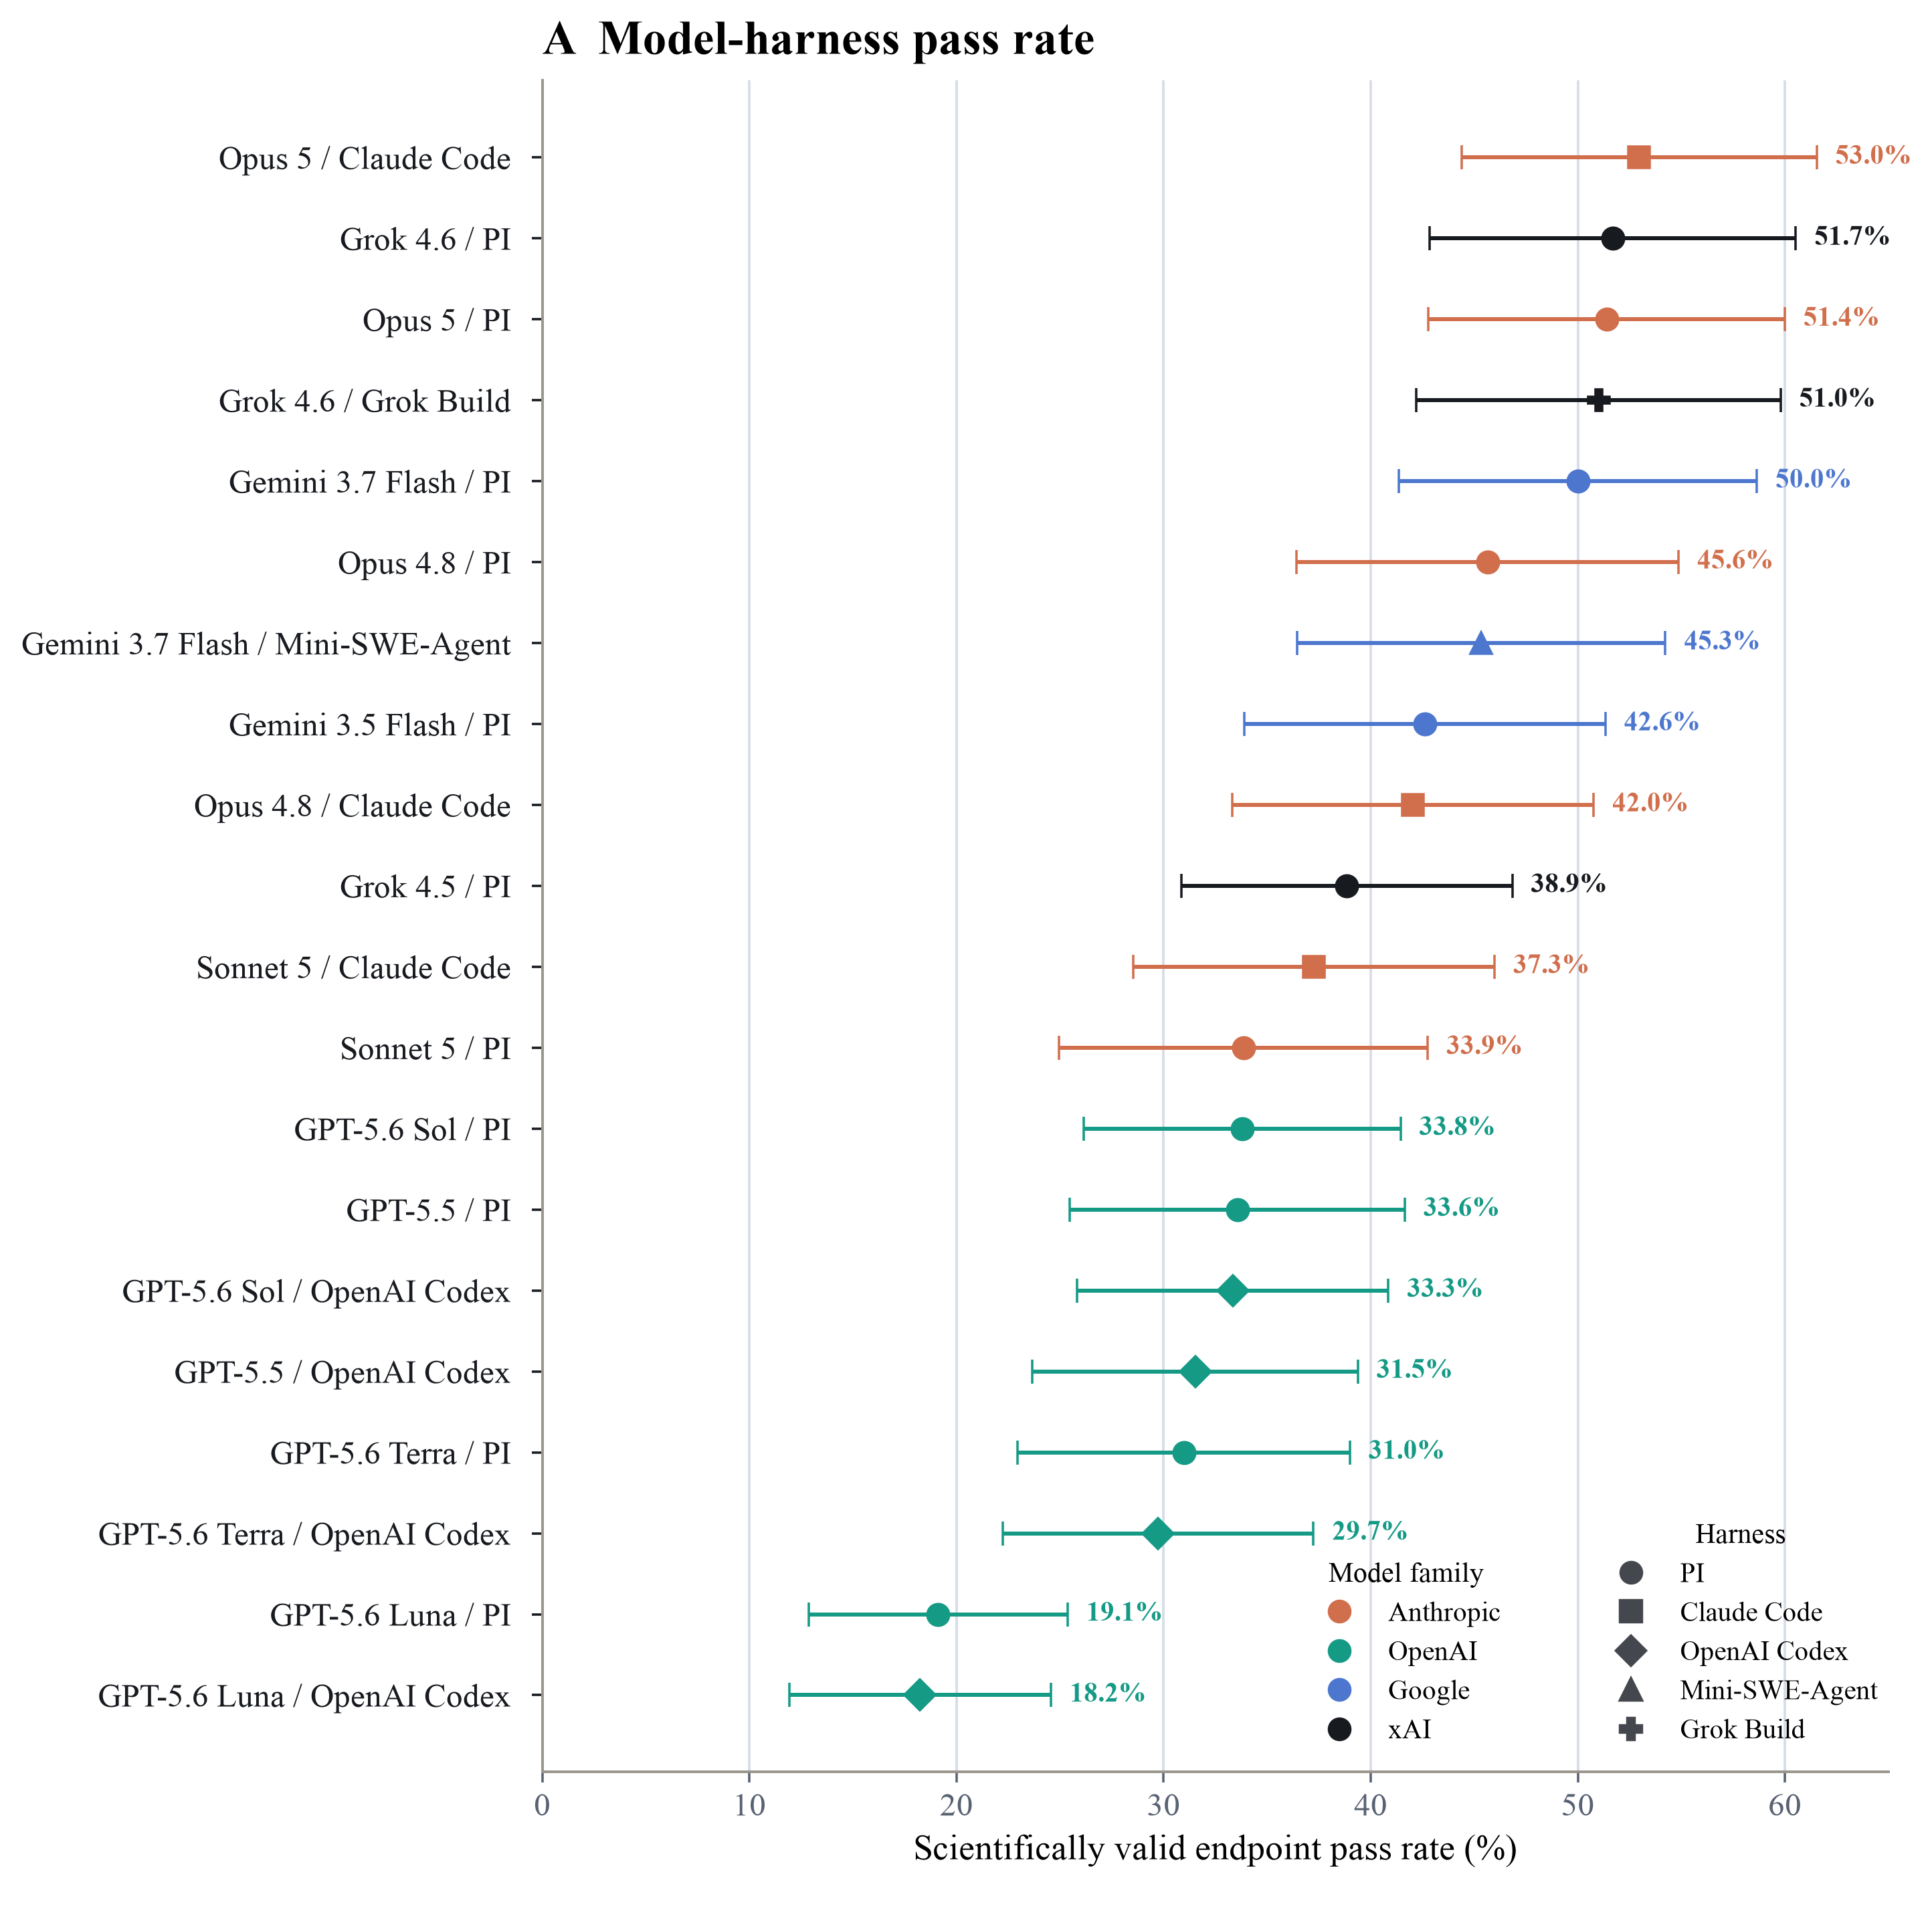
Across 20 model–harness configurations, even the strongest systems passed only about half of the attempts. Anthropic’s Opus 5 with the Claude Code harness topped the leaderboard with a 53% pass rate with models from xAI and Google following closely behind. In contrast, GPT-5.6 Sol using the PI harness lagged substantially behind the other frontier models, reaching only 33.8%.
Biologics discovery requires interpreting data in context
Biologics discovery for therapeutic applications is a multiparameter, context-dependent endeavor. When evaluating antibodies, achieving high affinity or any other desired properties, must be weighed against critical factors like specificity, structural stability, solubility, and expression levels – all of which collectively dictate a candidate’s development potential.

A clone can become enriched during display because it grows or amplifies efficiently rather than because it binds the target. An antibody can bind strongly to purified antigen but poorly recognize the same protein in its native cell-surface context. An apparent affinity advantage can instead come from avidity on a high-density cell surface. Changing valency or molecular geometry can alter function even when the underlying binding domains remain the same.
Deciding which of these measurements to act on is therefore the work that determines where a program should be allocating its resources. Productivity is far more sensitive to how well a decision gate correlates with real clinical utility than to how many candidates it can process; a tool that is fast but only weakly correlated with true biology spends the budget in false positives.
This is why benchmarks that focus on evaluating whether models reach accurate decisions rather than testing accuracy in a controlled context are important. This is exactly what we designed the Antibody Discovery Benchmark benchmark to test.
More resource consumption does not necessarily produce better results
Model harness configurations varied substantially in cost, token usage, and tool calls. Allocating more resources did not consistently improve performance.
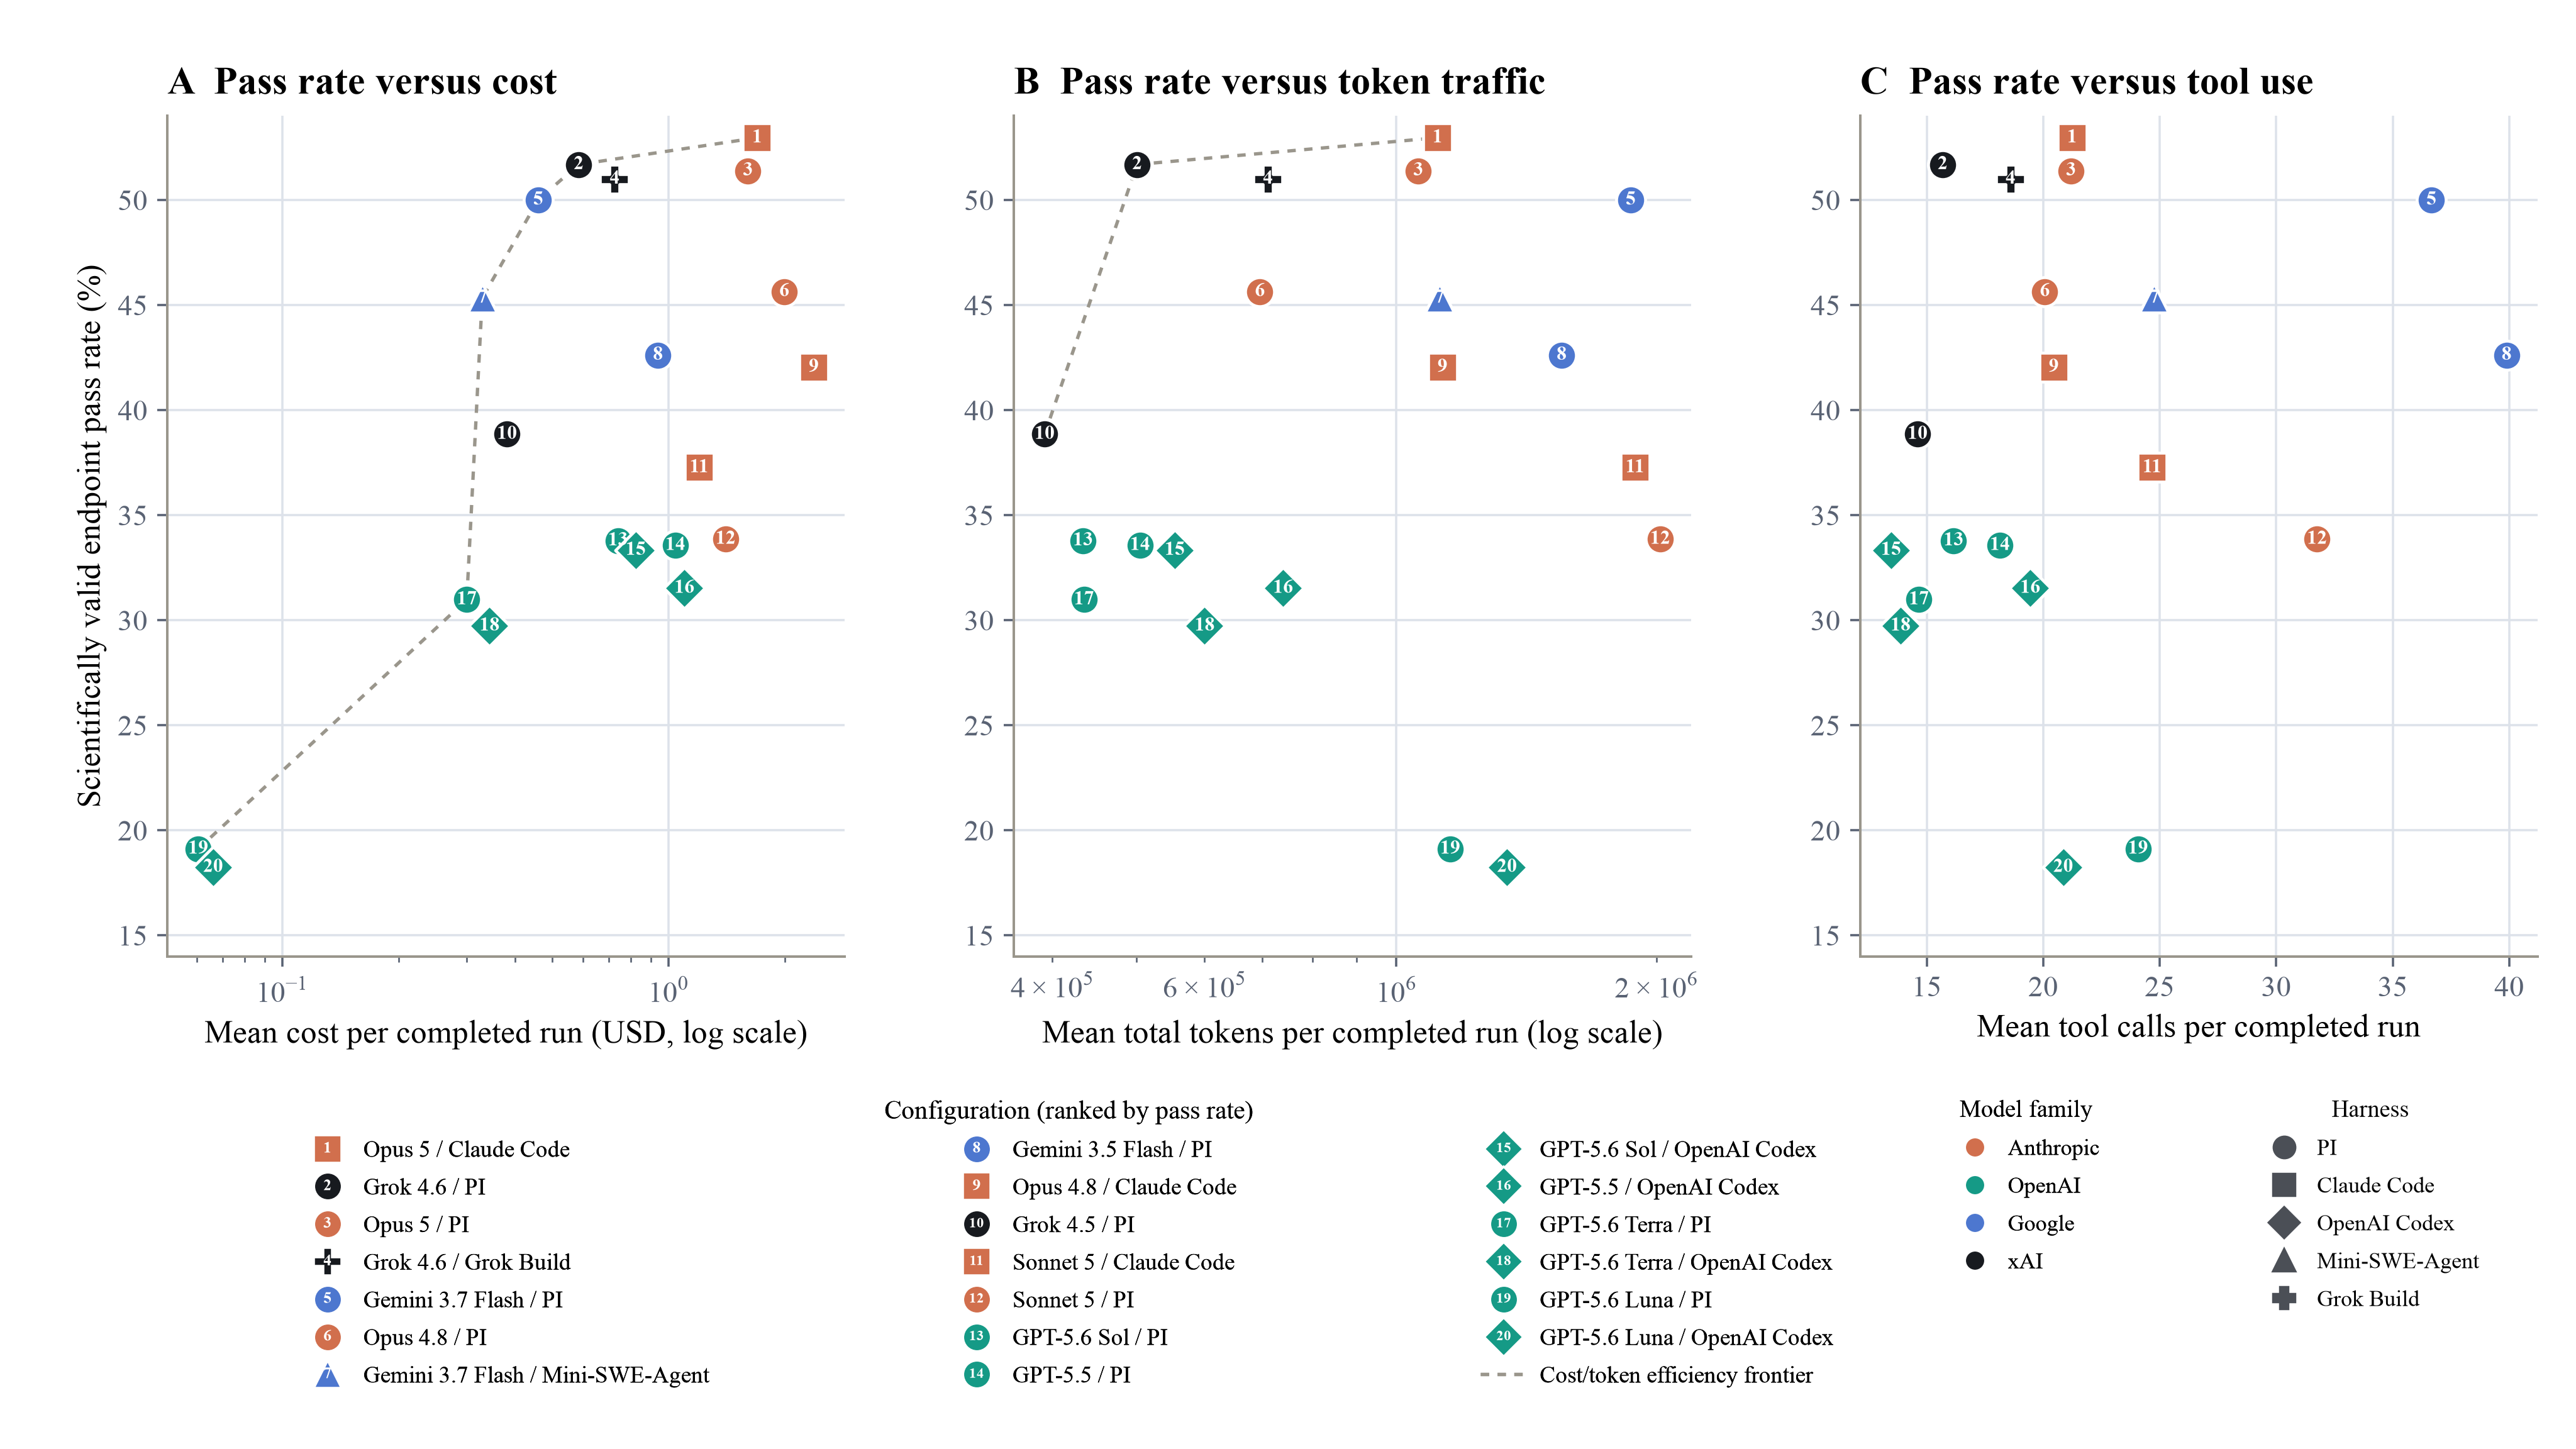
Opus 5 paired with Claude Code harness was the highest-scoring configuration, averaging about $1.68 per completed run, 1.10 million tokens, and 21 tool calls. Gemini 3.7 Flash with PI reached essentially the same accuracy at $0.46 per run, while using approximately 1.84 million tokens and 36 tool calls. Grok 4.6 with PI achieved similar results with slightly higher cost ($0.59), lower tokens (0.50 million) and fewer tool calls (16). Agents from OpenAI models used substantially fewer tokens and tool calls and performed much worse.
As an example, more reasoning did not reliably repair an incorrect scientific premise. In one evaluation, agents had to reconcile an inconsistency in experimental treatment records before comparing receptor responses across species. Opus 5 identified the inconsistency, reconstructed the correct experimental arms, and reached the correct result.
Gemini recognized the same inconsistency but retained the wrong arm assignment. It then performed considerably more computation on top of that decision, propagating the original mistake through the rest of the analysis.
This is an important distinction for scientific agents; resource consumption tells us how much analysis an agent performed, not whether it correctly framed the scientific question.
Models showed substantial differences in performance across the ten different biologics competencies
Opus 5 was strongest on target opportunity and therapeutic-hypothesis decisions, reaching 70.5%, and on cellular pharmacology and mechanism of action decisions, at 67.9%. Gemini 3.7 Flash showed a very different profile. It reached 72.2% on epitope, escape, and structural-mechanism problems, where agents had to combine competition experiments, mutational scans, escape profiles, and structural evidence.
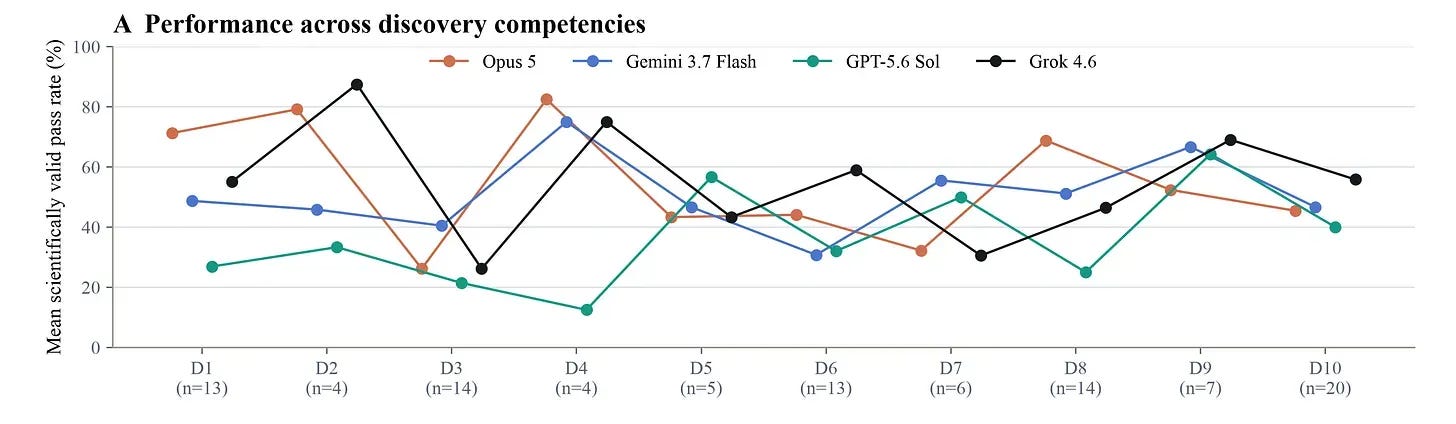
GPT-5.6 Sol was comparatively strongest on sequence, lineage, and enrichment analysis and on discovery engineering and next-cycle design. Meanwhile, some areas remained difficult for all models. Assay and screening decisions were challenging across all three leading model families, in addition to binding, kinetics, avidity, and specificity.
View the results and subset of evals/trajectories
Read the manuscript for the complete benchmark design and analysis
We regularly update our benchmark family with new models.
We also encourage researchers interested in what these benchmarks actually measure to inspect the released sample evaluations and agent trajectories.
This was a great read, and grounding every eval in real experimental evidence is what makes the leaderboard worth taking seriously.
Your Gemini example is the part that does the most work here. It recognized the inconsistency in the treatment records, kept the wrong arm assignment anyway, then built more computation on top of it. That pulls apart two skills a single pass rate folds together: noticing that the evidence conflicts, and letting that conflict change the decision. Your point about decision gates is about the second one. A gate that flags a problem but still passes the candidate spends the budget just like one that never flagged it.
It also reframes the cost finding. More tokens on a well-framed question is analysis; on a wrongly framed one, it is confident error at scale.
Now that the trajectories are released, it would be interesting to see how often failed runs spotted the key problem and then didn't act on it. That gap might say more about readiness for real programs than the headline 53%.